Decoding Token Economics: The AI Cost Revolution Underway
If 2023 was the "birth year" of large language models, and 2024 the "year of application explosion," then 2026 is fast becoming the "year of cost awakening."
More and more enterprises are discovering that AI isn't unaffordable — it's just that they're spending on it blindly. For a high-traffic application, the monthly token bill can differ by multiples depending on model selection, call patterns, and governance maturity — yet many companies can't even explain where the money actually goes.
This article breaks down the underlying logic of token economics from first principles, and offers a practical framework for enterprise thinking.
1. Token: The "Electricity" of the AI World
A token is the basic unit of text that large language models process. One token is roughly equivalent to 0.75 English words, or about 0.6–1 Chinese character — tokenizers vary by model: most Chinese models map roughly one token to one Chinese character, while OpenAI's tokenizers map about 0.6.
A token carries four layers of value at once:
• For model companies, it's a revenue unit — every token processed generates a billing event.
• For infrastructure providers, it's a compute unit — generating one token consumes a measurable amount of GPU compute.
• For developers, it's a cost unit — the cost of each call equals (input tokens × input price) + (output tokens × output price).
• For end users, it's an experience unit — more output tokens mean longer, more detailed answers.
Understanding these four layers explains why prices move the way they do — and where the headroom for cost optimization lies.
2. The Underlying Economics of Cost
The cost of a single inference can be summarized in one formula:
Single inference cost = (prefill compute + decode compute) × GPU cost per hour ÷ GPU utilization
GPU utilization is the single biggest variable in cost differences. Latency-first strategies reserve idle capacity and run at lower utilization; throughput-first strategies raise utilization through dynamic scheduling and batching, cutting per-unit cost. This is one of the core sources of price differences between providers.
Two counterintuitive patterns are worth noting.
First, longer inputs carry higher marginal cost. Prefill compute scales roughly with the square of input length — increasing input from 1,000 tokens to 4,000 tokens raises prefill compute by about 16×. This is why long-context models cost far more than standard models.
Second, output costs more than input. Decoding is generated token by token — every output token requires a full forward pass — while prefill runs in parallel batches. With GPT-4o, for example, output pricing is exactly 4× the input price.
3. Price Collapse: Three Waves of Dramatic Decline
LLM API prices have fallen far faster than expected, driven by three key waves.
The first wave came in early 2024, driven by open-source models. The release of Llama 3, Mistral, and others made self-hosting viable; the cost of deploying your own models fell well below closed API prices, forcing the whole industry to cut prices.
The second wave arrived in mid-2025, driven by maturing inference-optimization techniques. Speculative decoding uses a small model to draft and a large model to verify, speeding up generation 2–3×; PagedAttention borrows the paging idea from operating systems to manage the KV cache, sharply improving GPU memory utilization; continuous batching uses dynamic batch scheduling so GPUs never sit idle, lifting utilization from roughly 40% to over 70%. Together, these techniques dramatically reduced the cost of a single inference.
The third wave hit in Q1 2026, driven by cost-effective Chinese open-weight models entering the market.DeepSeek, Qwen, and GLM entered at extremely competitive prices, pushing API price thresholds even lower.
Using September 2026 input prices for mainstream models as a reference: lightweight models run about $0.15–0.30 per million tokens**, mid-tier models about **$0.50–1.50, and flagship models about $2.00–3.00. Multiple price gaps separate the tiers, giving enterprises ample room to match models to tasks.
After three waves of cuts, the unit cost of flagship-grade inference in 2026 has fallen dramatically compared with 2023.
4. Enterprise Cost Reduction: A Five-Layer Framework
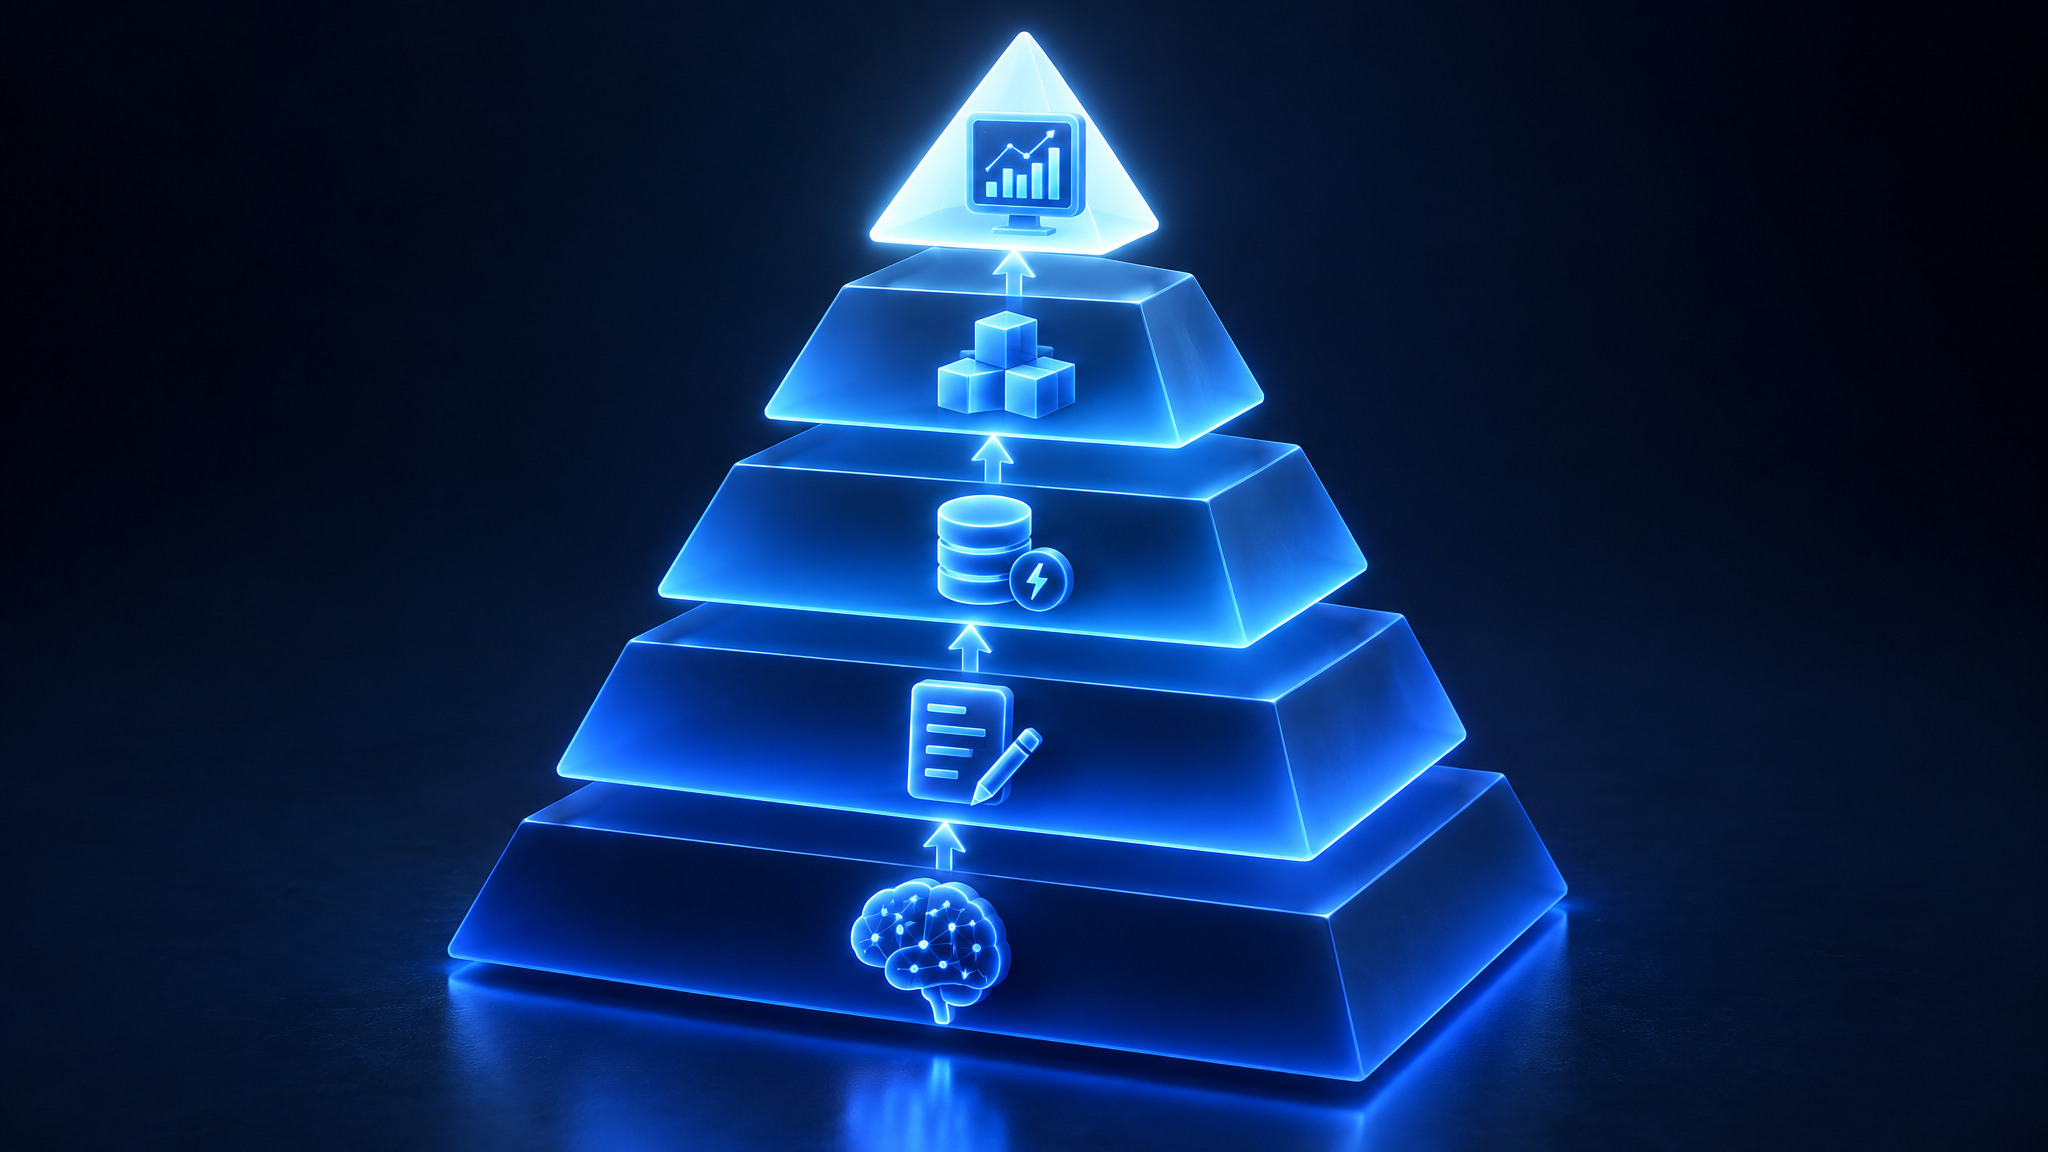
Prices are falling, yet total enterprise AI spend keeps rising — because usage growth typically outpaces price declines. Systematic cost reduction can be approached across five layers.
Layer 1: Model selection. Build task-complexity tiers: lightweight models for simple tasks, flagship models for complex ones. This is the highest-ROI optimization — no architecture changes needed, just a routing decision before each call.
Layer 2: Prompt optimization. Trim redundant content in system prompts, limit few-shot examples (two or three usually suffice), cap max_tokens to avoid pointless long outputs, and use structured output to reduce retries caused by parsing failures.
Layer 3: Caching and batching. Apply semantic caching to high-frequency repeated requests so similar questions return cached answers; batch non-real-time tasks, since batch inference costs far less per unit than individual calls; and leverage provider prefix caching so identical system prompts are billed only once.
Layer 4: Architecture optimization. In RAG scenarios, retrieve first and generate second to shorten input token length; in agentic scenarios, use small models for planning and large models for execution; and periodically compress multi-turn conversation history to keep context from ballooning.
Layer 5: Governance and monitoring. Establish cost allocation by department or project so every business line owns its AI costs; set alerts for abnormal usage — a sudden spike in call volume may signal a bug or an attack; and regularly review the most expensive endpoints for targeted optimization.
The savings figures for each layer above are industry estimates and vary by business scenario. But the core takeaway is this: every layer of this framework depends on stable, flexible infrastructure to support it.
5. DataEyesAI: The Infrastructure for Enterprise AI Services
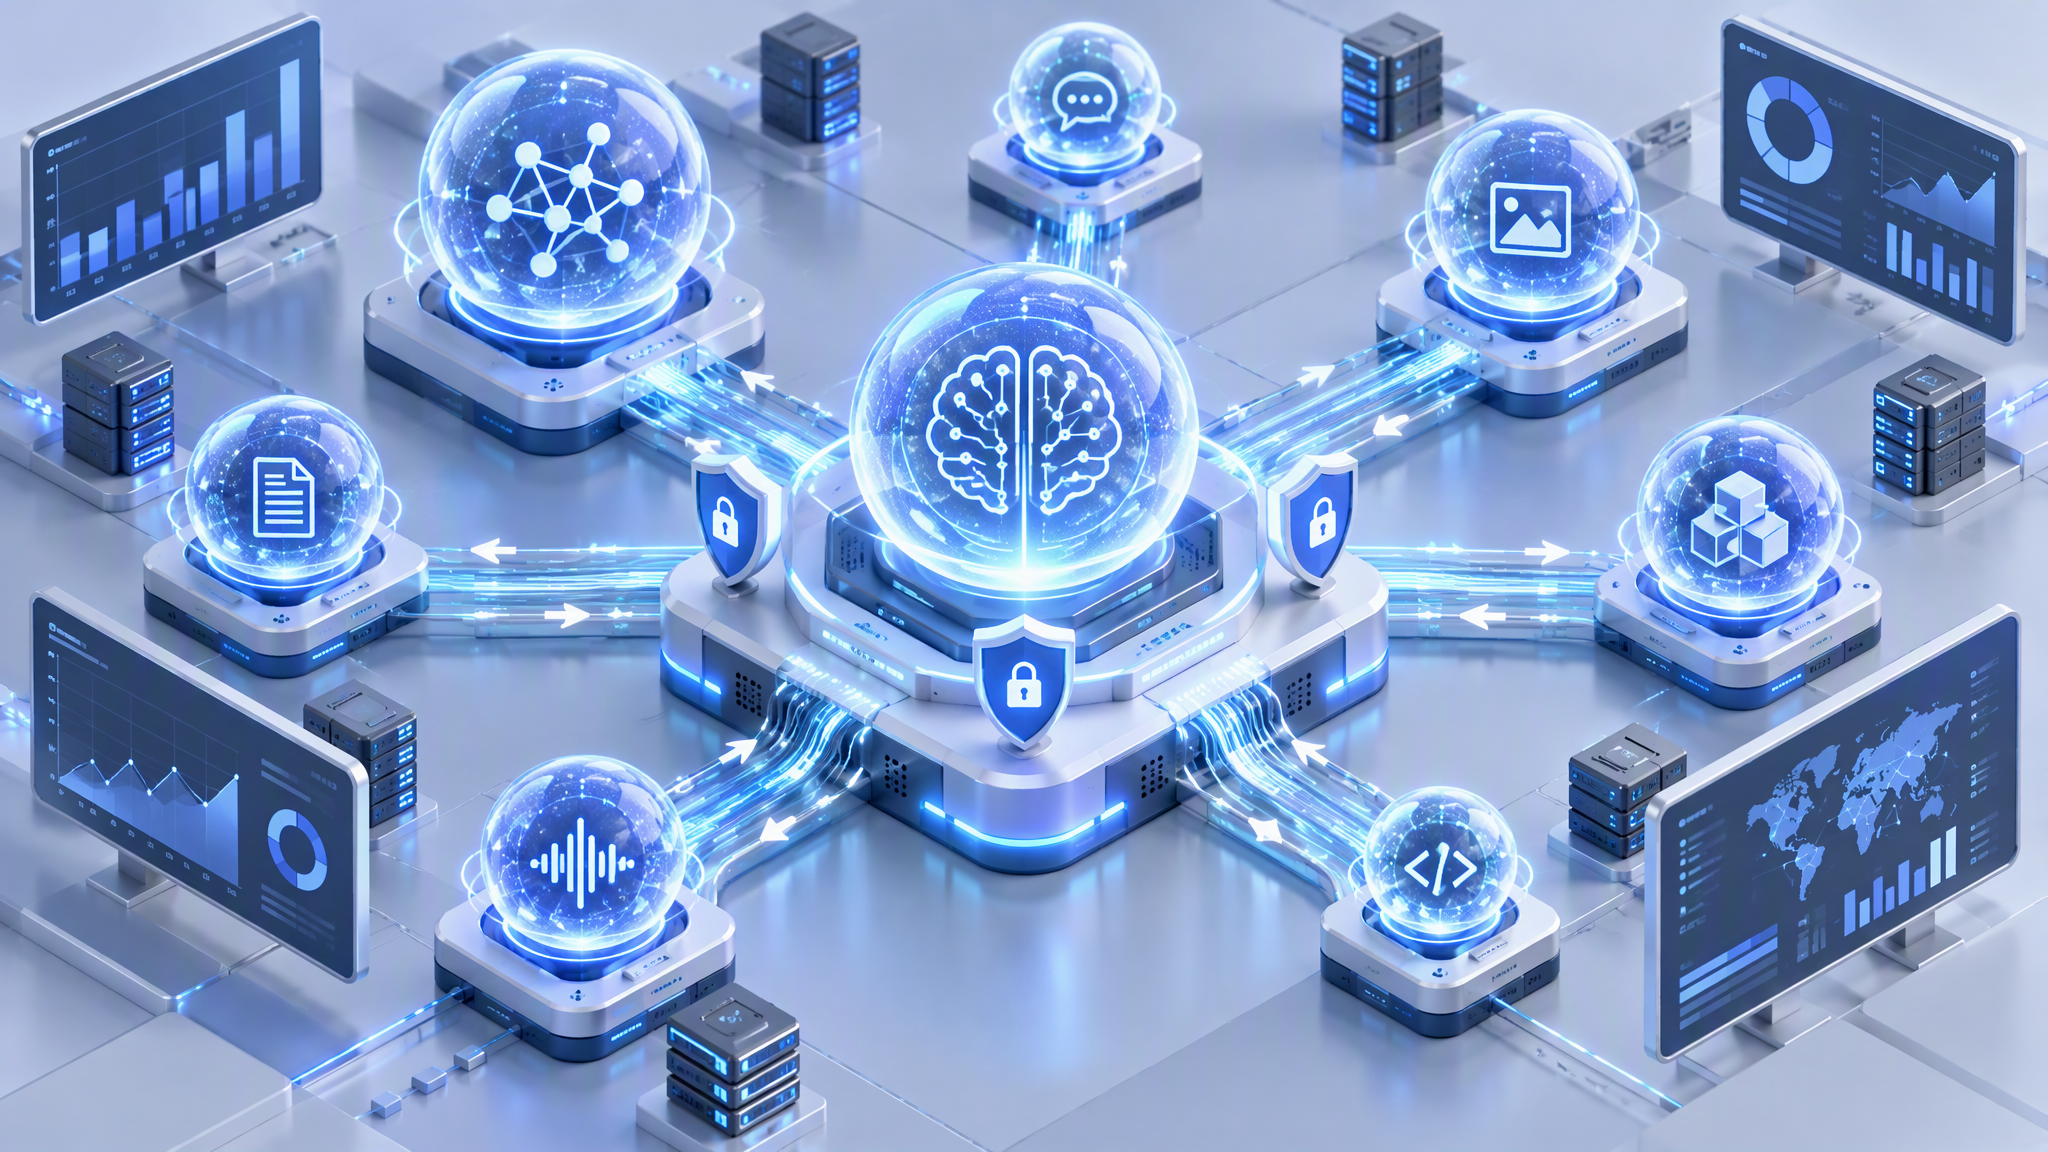
As token costs become a top enterprise concern, DataEyesAI is committed to providing one-stop infrastructure for model access, governance, and metering — helping enterprises achieve controlled costs, reliable operations, and transparent management in their AI rollout.
Multi-model access: more choices make cost reduction possible. Cost reduction presupposes choice. DataEyesAI offers aggregated multi-model access covering mainstream general-purpose LLMs, multimodal models, and embedding models. Enterprises no longer need to integrate and maintain multiple platforms separately — a unified interface lets them flexibly call different models. The platform is compatible with mainstream API formats, lowering integration and migration costs, and turning "match the model to the task" from a concept into practice.
Intelligent routing strategies: smarter model matching. Version 2.4 of DataEyesAI introduced API routing strategies, enabling enterprises to configure model invocation rules based on their own business needs for more flexible scheduling and traffic management. Enterprises can design routing strategies suited to their scenarios, balancing cost, quality, and stability. Specific configuration options and capabilities are subject to the actual features of the DataEyesAI console.
Transparent metering and governance: make costs visible. Cost reduction presupposes knowing where the money goes. DataEyesAI provides comprehensive usage metering and cost analysis, helping enterprises clearly understand the usage and spend of their AI calls. The platform supports multi-dimensional usage queries and statistics, so enterprises can view and analyze AI call costs from different angles, build fine-grained cost management, and turn AI spend from a black box into a clear ledger.
Stability and reliability: business never stops. No matter how cheap a model is, an unavailable service is worth zero. DataEyesAI focuses on service stability through multi-route access and failover mechanisms that mitigate the impact of a single model or route failure, keeping enterprise AI applications running.
Security and compliance: use with confidence. DataEyesAI values data security and compliance, providing safe and reliable AI calling services. The platform supports enterprise-grade permission management and access control, and can provide deployment options tailored to enterprise needs to meet security and compliance requirements across industries. Specific security capabilities and deployment options are subject to official product documentation.
From model access to routing strategies, from usage metering to stability assurance, DataEyesAI delivers one-stop infrastructure around the core needs of enterprise AI adoption — helping enterprises use AI affordably, reliably, and transparently.
🚀 Learn more:
Visit the DataEyesAI website at https://www.dataeyes.ai/ for product details and the latest updates.
New users can register to experience all platform features — start your enterprise AI cost-reduction journey today.
6. Conclusion: Cost Isn't the Problem — Cost Awareness Is
The cost of large language models will keep falling. But once AI becomes cheap enough, usage explodes and total spend rises anyway — just as electricity prices fell a hundredfold while humanity's total consumption grew a thousandfold.
The real competitive advantage isn't how expensive a model you use — it's whether you've built fine-grained AI cost management.
The token economics revolution is, at its core, an efficiency revolution. And efficiency has always been the hardest currency in business.
You might also be interested
DataEyesAI 2.4 Update: Wallet Redesign, Smart API Routing & Auto-Renewal
The DataEyesAI dashboard has been upgraded to version 2.4.
For Developers: The Era of Model Freedom is Here! DataEyesAI Launches with 5 Free Models + 9 Special Offer Models!
DataEyesAI Model Plaza is now officially live.
DataEyesAI V1.0 Official Launch
DataEyesAI V1.0 is officially launched.